

I don’t read code anymore.
I define the task and its constraints. Agents produce and verify the evidence. An oversight model checks that evidence, and I question it about the exceptions and the calls that need my judgment.
The abstraction layer for humans has changed. Agents are frontline coders now.
You should not be reading the code.
No seriously, unless you’re working on truly critical infrastructure, life-threatening, this-shit-cannot-go-wrong code, you, the person reading this, should step back from reading code. You are slowing your agents down. You are slowing yourself down.
Be more ambitious. Lead a robot army.
As the general of your agent army, your job is logistics. You are coordinating divisions of agents, orchestrating their movements in your campaign, ensuring they receive the provisions (context) they need, and positioning your resources (task boundaries, permissions, etc.).
Pick your favorite metaphor. Build your AI factory, your Gas Town.
Stop reading diffs.
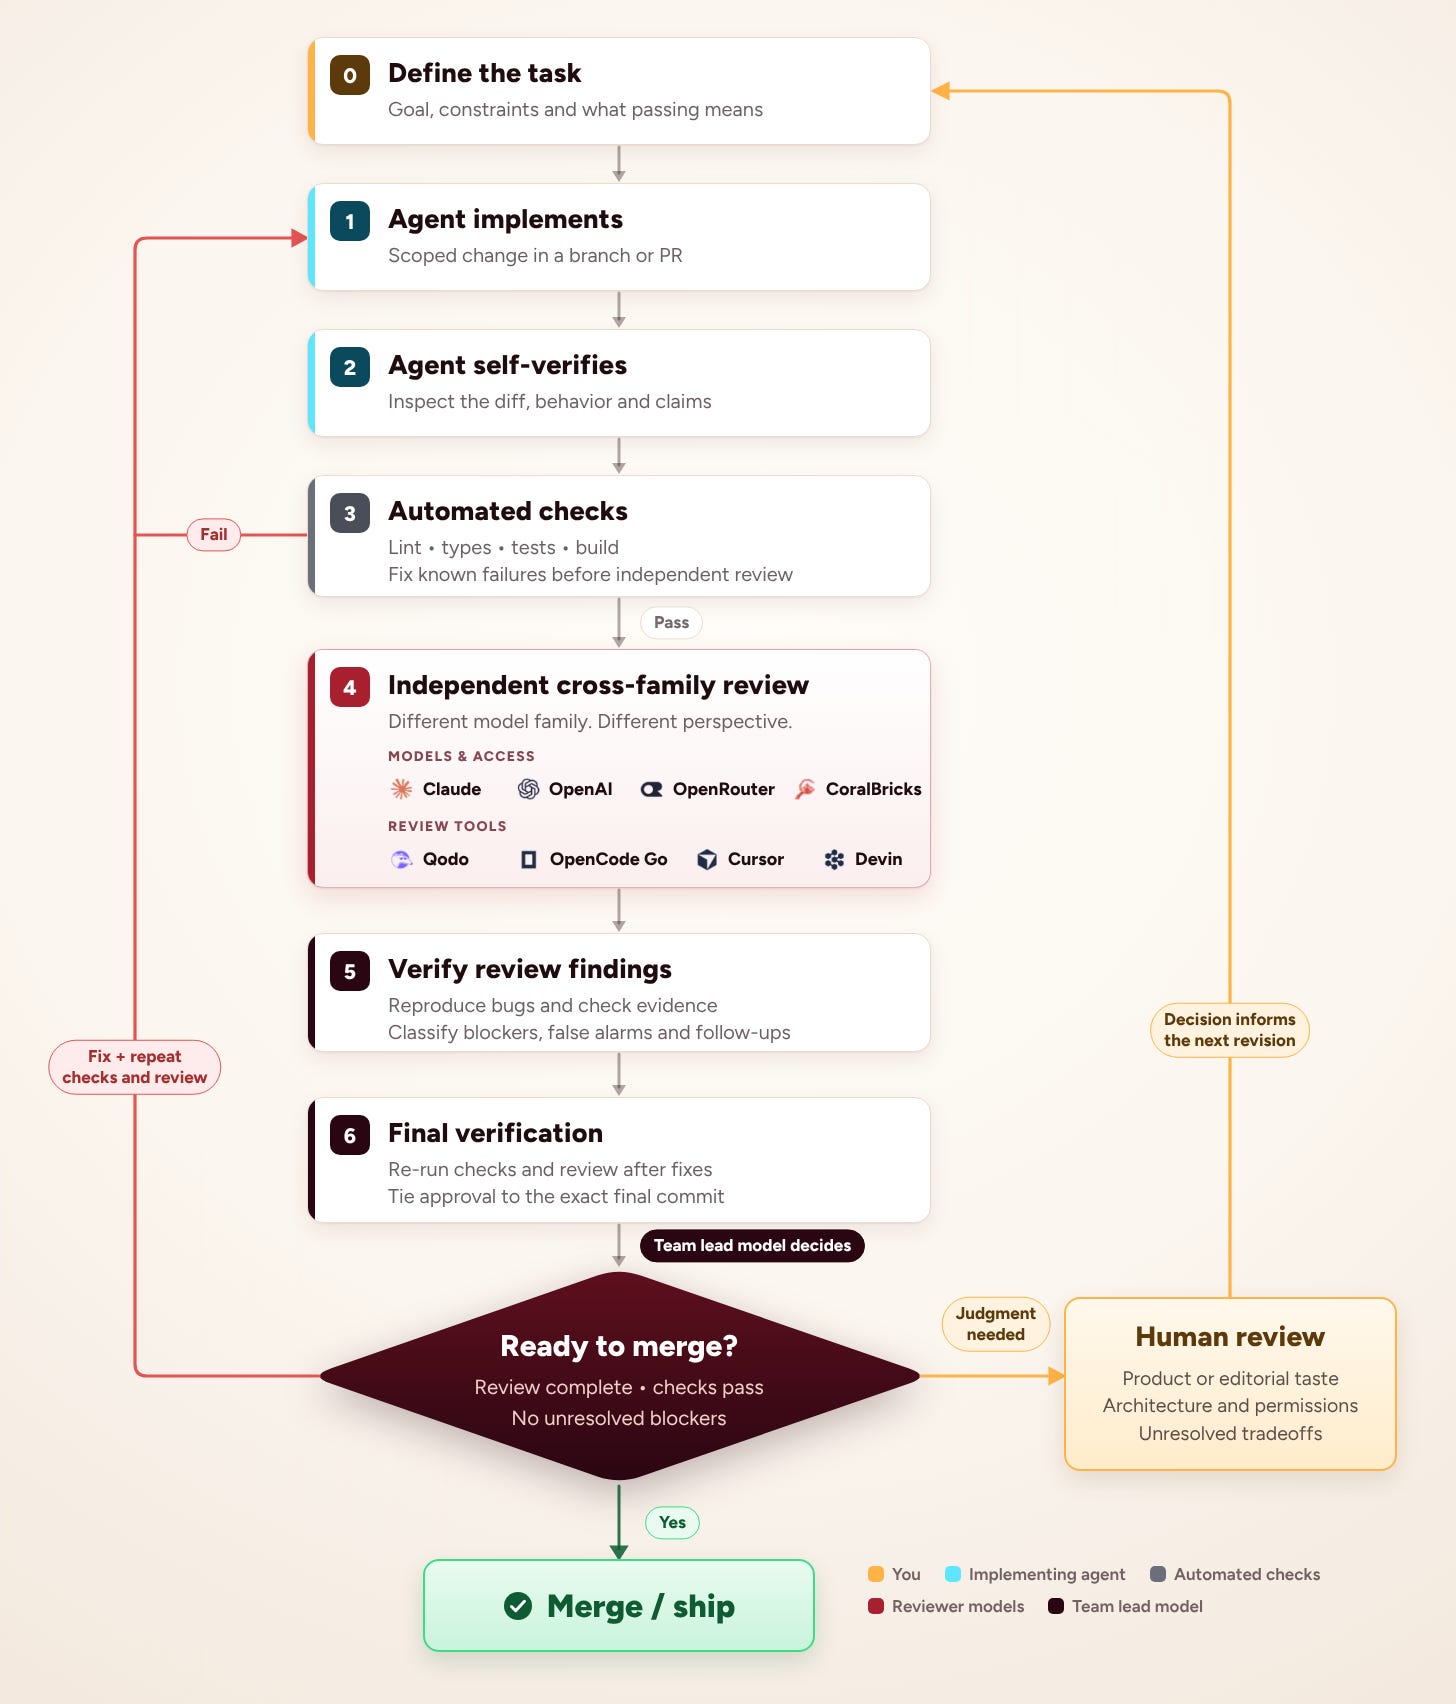
Your agents do that for you. Your coding process and review loop should look something like this:
This newsletter is sponsored by Walrus Memory, the portable memory layer for AI agents.

Your agent’s memory and your data usually live in different places, and both end up tied to one app or one provider.
Walrus Console puts them side by side: agent memory, storage, encryption, and renewals in one place. Protections travel with each file, and anyone can independently verify its integrity.
Connect your data to Claude Code, Codex, and Cursor through MCP or an API key, and put it to work across apps and AI tools without syncs, migrations, or vendor lock-in.
Cheap checks come first
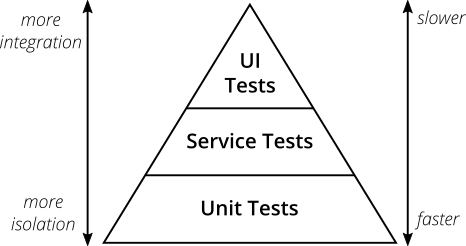
In my code review process, the implementing agent starts by inspecting its changes and running the relevant automated checks: lint, types, tests, build. Teams have done this for years: the practical test pyramid puts fast tests early and slow tests later.
Known failures then loop back for fixes before we spend more time and tokens on independent review. After each fix, the affected checks and review run again.
My current setup: Often, I’ll have a team lead agent driving this process. Right now that team lead is usually an Opus 5.5 model with access to multiple models for coding support: Claude models, GPT-6.1 Sol, and DeepSeek V4.1 Flash via CoralBricks for fast, cheap frontline work (disclosure: I have consulted for them).
In Building Effective Agents, Anthropic recommends clear stop conditions (such as iteration limits) and grounding progress in tool results/code execution. With earlier checks and specific iteration loop rules set on a per-project basis, I adopt that same approach.
Anush Elangovan described his own version of this on the Chain of Thought Podcast. Before implementation, he defines the test framework and asks his agents for more tests. For his ISA rewriter, that meant using compiled kernels as a test set and requiring them to pass on every commit. Anush treats tests as the gate for his sandbox: when correctness or performance falls short, make the requirement explicit in the harness and let the agent iterate. This principle is useful here: define what passing means before asking another model to review the result.
Once checks pass, code proceeds to a focused cross-model family review.
Independent cross-model family review
For independent review, I want a different model family. If Codex implements a change, Claude can bring another perspective. Open models through other providers are part of the mix too and for certain high-value repos, like my internal Chain of Thought Podcast editing harness, I require multi-model review for many changes.
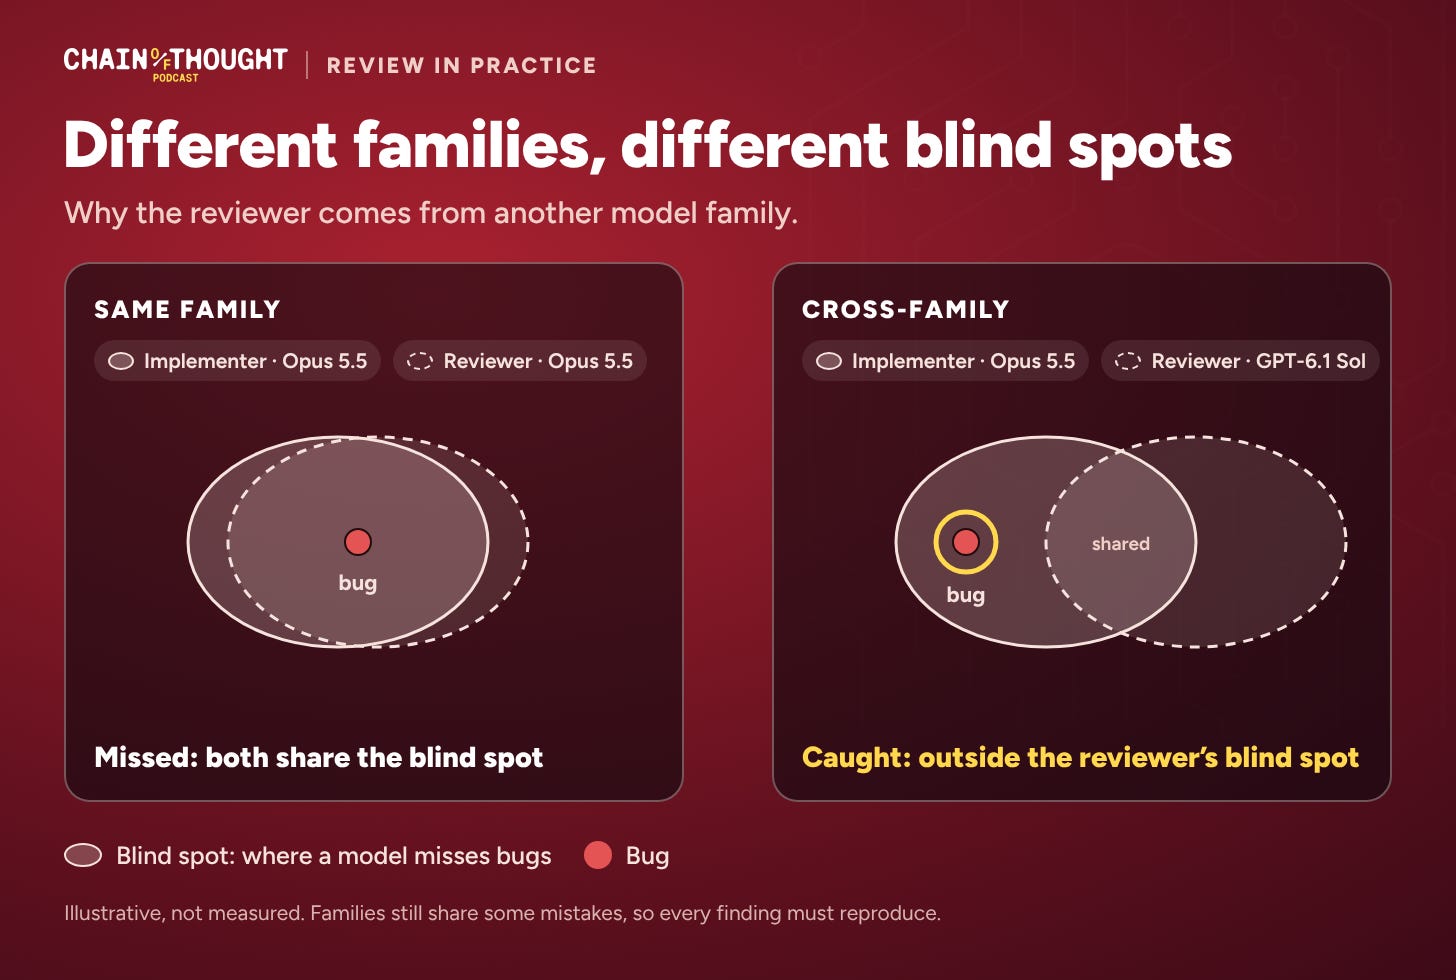
The idea is to reduce shared blind spots. I use a different model family (for example, having GPT-6.1 Sol review code from Opus 5.5) to challenge assumptions the implementing model may share with another instance of itself. Different model families can still make the same mistake, so agreement has to rest on evidence, not on models deferring to each other. Research supports mixing model families, and also warns against over-reliance.
Across more than 350 models, when two models both got a question wrong on one leaderboard, they gave the same wrong answer 60% of the time, and larger, more accurate models had highly correlated errors even across providers (Kim et al.). In multi-agent debate, models often abandon correct answers to agree with their peers (Wynn et al.).
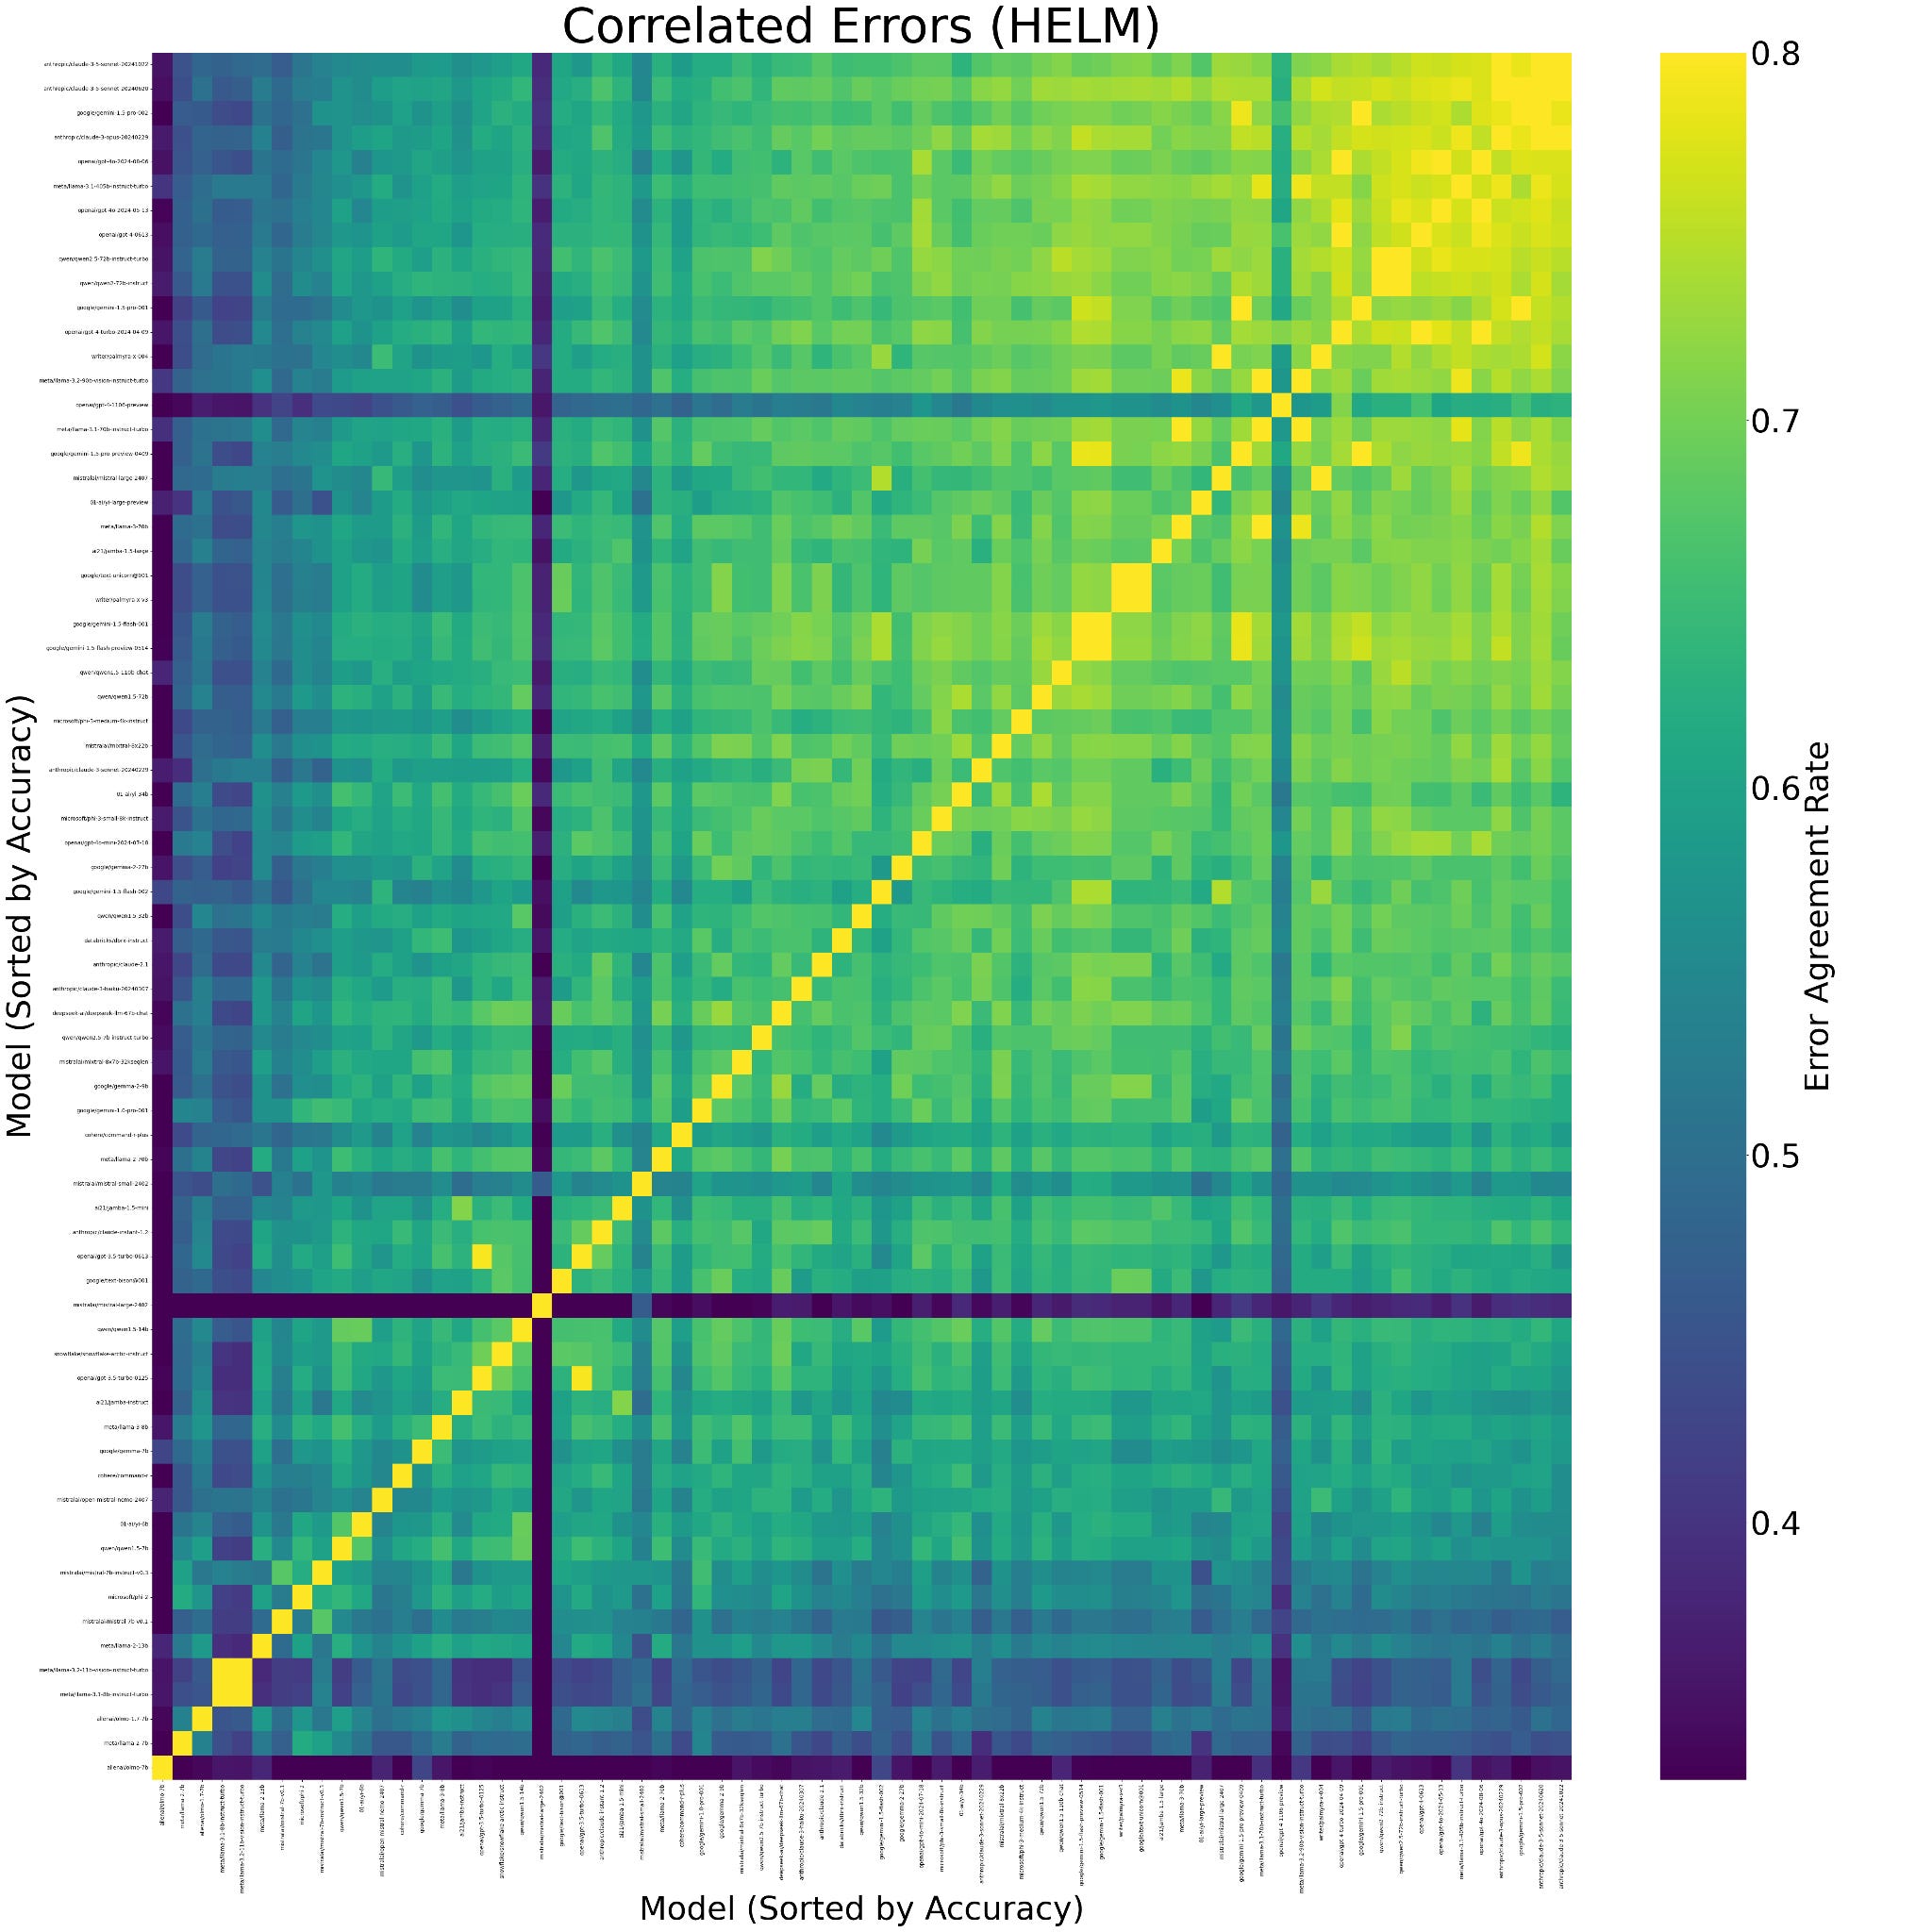
Prediction: As models from the same model family are increasingly being used to teach other generations of models via distillation and recursive self-improvement (RSI), I expect frontier labs to spend increasing amounts of effort identifying and addressing potential cross-generational biases. We may see major gains here that reduce shared mistakes and lower the value of outside model-family consultation, but for now, I still want a different model family challenging the work, with evidence to support its findings.
Using automated AI reviews
As a tangible example, I built and maintain avoid-ai-writing, an open source agent skill for auditing and rewriting AI prose with tens of thousands of users and more than 5k stars. Qodo (the AI code review tool) reviews its pull requests.
In a recent contributor PR, Qodo caught a bug in the tests: they could print “FAILED” and still pass. These kinds of checks are why mutation testing matters—model reviewers need to examine whether our tests can fail.
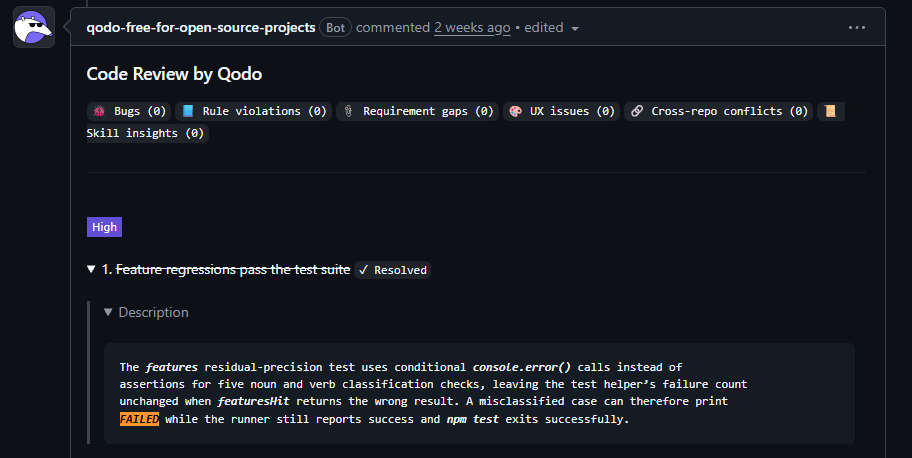
The PR replaced assertions with console.error() in five checks. They logged incorrect results without failing the test. Qodo flagged the problem, and the fix restored assertions.
That example explains why my code review loop includes both automated checks and independent review. The reviewer needs to examine what the tests establish, including whether they can fail.
There is also a reason for independent review: see this example of another PR on avoid-ai-writing. Two independent reviewers, Qodo and Devin, caught fixes the original contributor’s submission had missed.
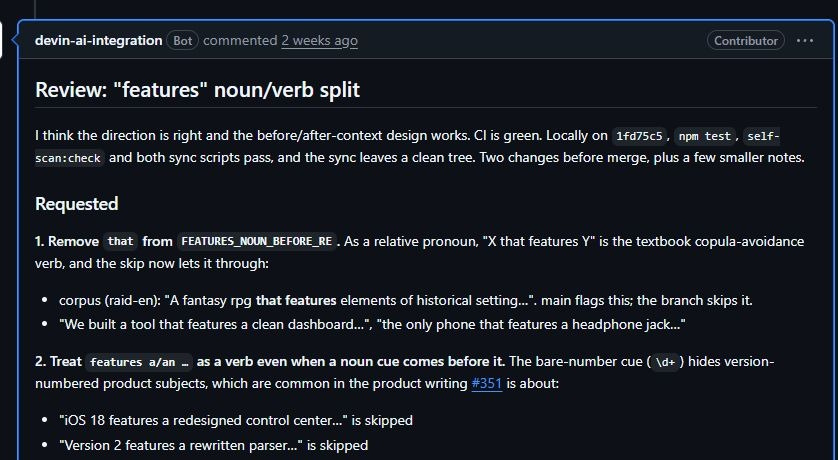
The review also caught a highlighting bug: a noun use was highlighted because a later sentence used the same word as a verb.
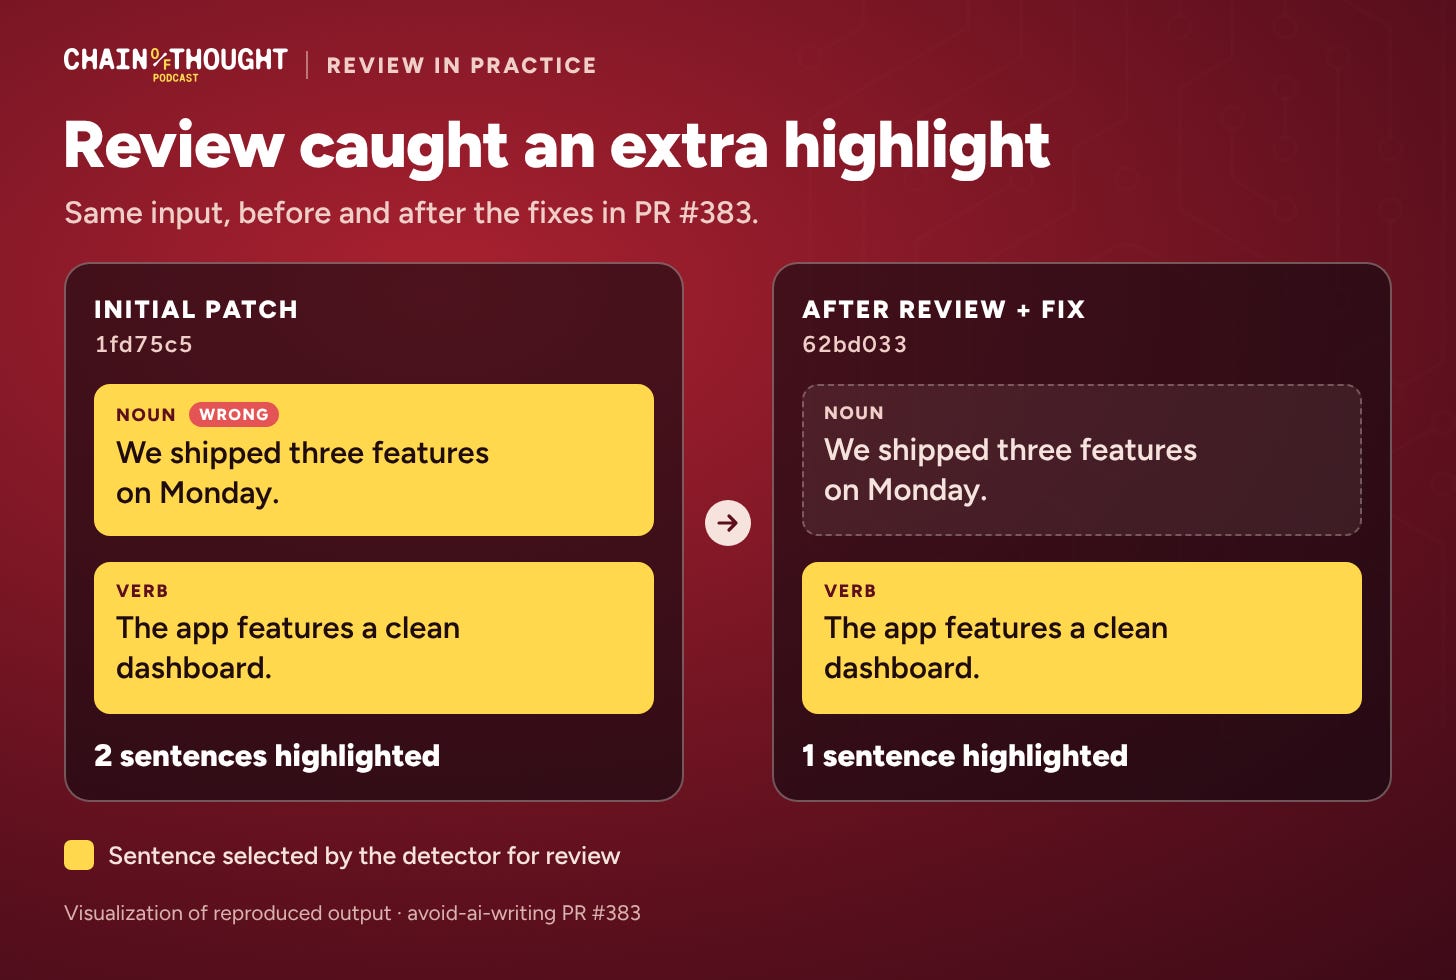
Yet our checks and review findings still need to survive reproduction before they drive a merge decision. Someone still has to inspect the implementation and the checks themselves. In my loop, that’s an oversight model, and I question it until the evidence holds up. Only in extreme circumstances am I reading the diff myself.
Verify the reviewer too
Give each AI reviewer the requirements, the diff, and enough repository context to investigate. Let it form its own initial view before showing it the other agents’ verdicts. The lead can then reconcile the findings against the code.
During a preprocessing review on avoid-ai-writing, one reviewer used ‘word’.repeat(500) as a supposed 500-word test input. That creates one long word. (JavaScript did exactly what it was asked to do.)
Other findings didn’t hold up either: some described bugs that existed before the PR, and some flagged a mode the measurement code never uses. The executing agent checked those claims and rejected or narrowed them. A reviewer saying “do not merge” kicked off an investigation by other agents.
There were real bugs too. A size limit meant for paragraphs was silently deleting headings from long documents. The fix separated cleaning up the text from choosing which paragraphs to check. Reproducing each claim is what told the real bug apart from the bad test and the old behavior.
A useful finding identifies the input, expected behavior, actual behavior, and code responsible. Where practical, the reproduction becomes a regression test. An agent that only inspected the code needs to say so. “I ran it” needs a command and a result behind it as attestation.
Have AI review the commit you’re actually merging
Fixes change the thing you reviewed. Approval of an earlier version cannot cover code the reviewer hasn’t seen.
The final review record on PR #383 names the exact commit and three completed reviews: Claude Sonnet, Thinking Machines Inkling Small, and Cohere North Mini Code. Those models read the code but didn’t run it. The lead model separately ran the affected tests and recorded the results, including forty new paired test cases and seven passing GitHub checks. Earlier local timing failures were disclosed rather than represented as green.
A timed-out review is an incomplete review, and a passing test on a previous commit leaves the new changes unverified. Consensus across three agents still leaves you with the job of checking what their agreement rests on.
The review record should make the merge decision inspectable:
Name the exact commit and the models that reviewed it.
Link each accepted finding to its reproduction and repair.
Record what actually ran, with commands and results.
Separate remaining defects, baseline failures, and decisions that need a human.
Whenever possible, use an oversight model (your chief of staff) and only consume the summary + evidence chain personally.
Keep the evidence when you change models
Cross-model family review also creates a handoff problem. The next agent needs the requirements, repository constraints, and observed failures. I want that record available outside any one chat, with enough provenance to check how a decision was reached. A stored approval of yesterday’s commit cannot approve today’s changes.
This is where portable memory becomes useful. In our Chain of Thought conversation, Walrus’s Kimberly Logan described why switching models or agent tools should not mean starting over. Carrying context and memory forward can save repeated explanation (I’ve experimented with this in my agent-context-os project). The receiving agent still has to test whether a remembered claim applies to the code in front of it.
Human judgment stays in the process for product engineering and direction, editorial taste, architecture, permissions, and unresolved tradeoffs. Laurie Voss described the new job of software engineers on Chain of Thought as understanding what users need and directing agents to build it. That is where I want to spend my time: as a product engineer.
Leading a robot army means defining the work, equipping agents to verify it, and deciding when they need to come back to you. If I have to manually reconstruct what happened at every handoff, I’ve built more work for myself. The review loop should return a recommendation I can inspect and evidence the next agent can use.
Agents code. Humans steer.
Are you still reviewing code? What does your process look like?
Disclosures: I have consulted for CoralBricks, one of the model-access providers included in the accompanying diagram. You can use my referral code to receive an additional $5 credit (for a total of $25 in free credits) when you get started.
I also receive free automated PR reviews from Qodo on my avoid-ai-writing project via their ‘free for open source’ program (if you maintain an open source project, you should check it out).
Would you merge this?
Try this three-minute fictional review exercise: inspect an agent’s patch and decide whether you would merge it. What would you check before approving the change?
ICYMI: Understanding Engineering Metrics in the Agentic Era
I explored the metrics behind the new AI factory with Sonar CTO Andrea Malagodi. We discuss code verification and governance, and how to interpret metrics and measure the value of work as velocity accelerates. We also cover where Andrea finds human review useful, and how to effectively roll out AI tooling at enterprises where building these review loops can have challenging change management implications.
Watch the full conversation on YouTube, check out the transcript, or listen on your podcasting app of choice.
Thanks for reading, and let me know what you’d like to hear about next.
Cheers,
Conor
PS - if you read all the way to the end and haven’t already subscribed - I think you should!